

Benchmark · one prompt · one run each
AI Image & Video Model Benchmark (November 2026): Same Prompt, Every Model
We ran one photo prompt on 19 image models and one text-to-video prompt on 8 video models, kept every first result, and wrote down what each one cost and got wrong.
Text: 7 of 19 kept the labels readable · Video: Seedance 2.0 Mini followed the camera move
Checked
Made with Kenerate
On this page
Quick answer

Which AI models handled the same prompt best?
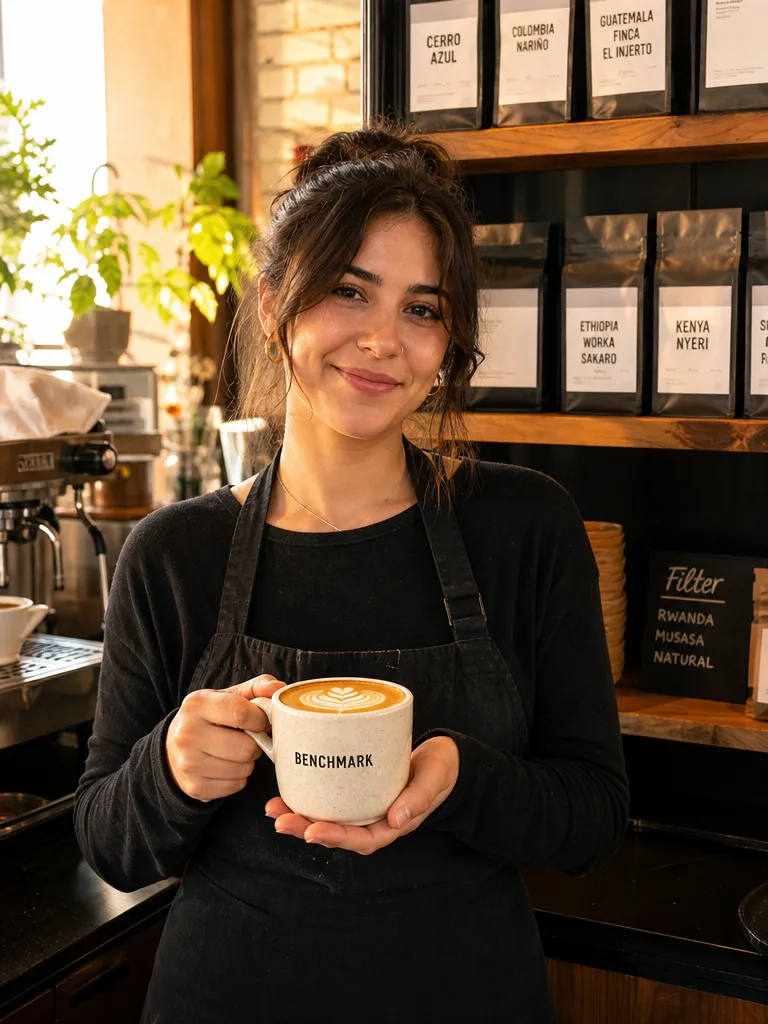
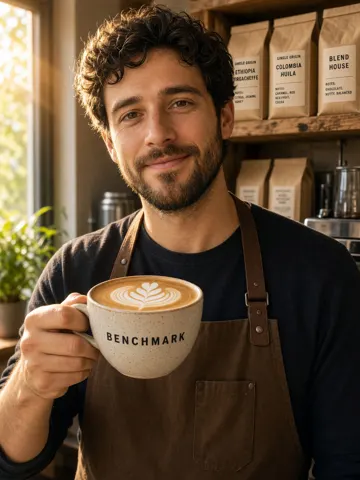
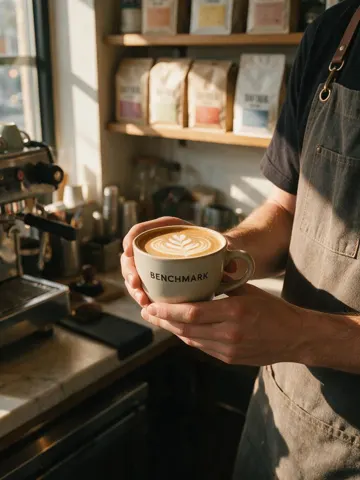
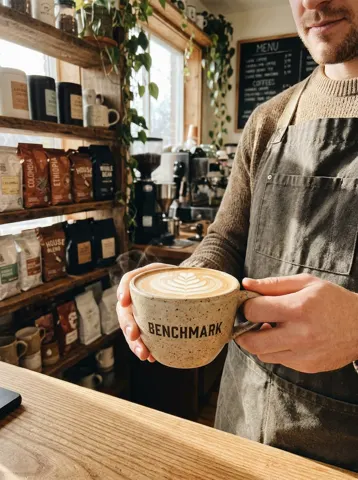
We gave 19 AI image models the same photo prompt and 8 video models the same text-to-video prompt, one run each, on 2 November 2026. All 19 image models spelled 'BENCHMARK' on the cup; the real split was the shelf behind it: only 7 produced readable coffee-bag labels (GPT Image 2, GPT Image 2.5 Sunburst, Nano Banana 2 and 2.1, Seedream 4.5, Recraft V4.1, Grok Imagine Image 2.0). GPT Image 2.5 Sunburst did it for 7.2 credits. For video, Seedance 2.0 Mini followed the 'slow tracking shot' best and Kling v3 Standard had the most physical water. It's one prompt and one run per model, so read it as a snapshot, not a ranking.
Key facts
- Image models tested
- 19, one run each
- Video models tested
- 8, text-to-video, silent
- Date
- 2 November 2026
- Spelled 'BENCHMARK' on the cup
- 19 of 19
- Readable bag labels
- 7 of 19 (3 partly)
- Credits per image
- 3 to 30
- Credits per 4–5 s clip
- 30 to 126
- Total spent
- 912.3 credits
Methodology
How we tested
Same words, same settings, first result only. Nothing was re-rolled, cropped or retouched.
On this page
The prompts
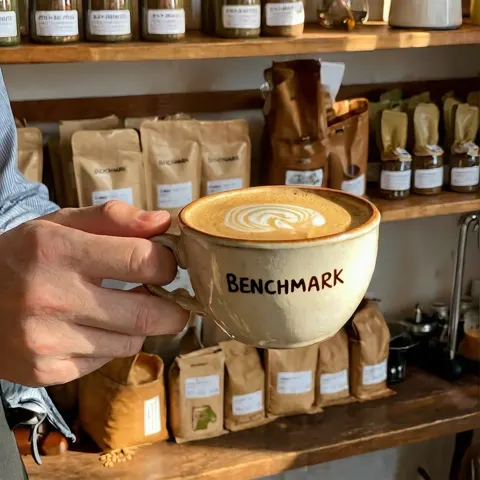
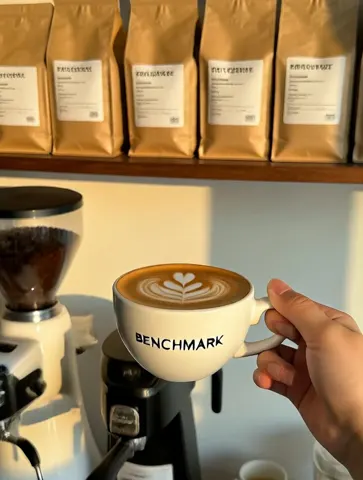
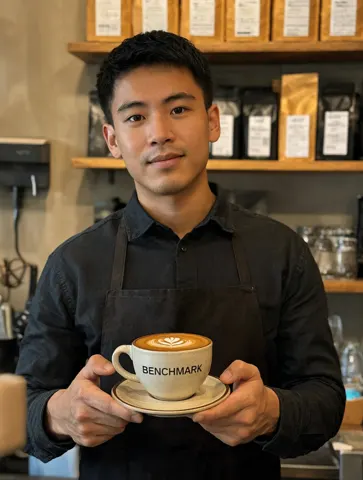
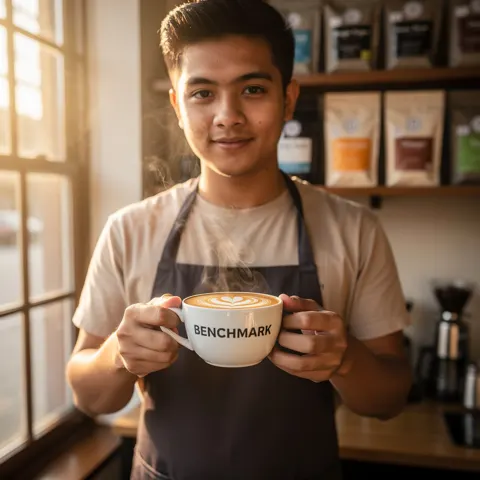
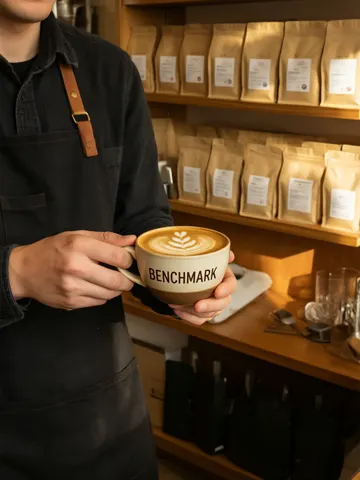
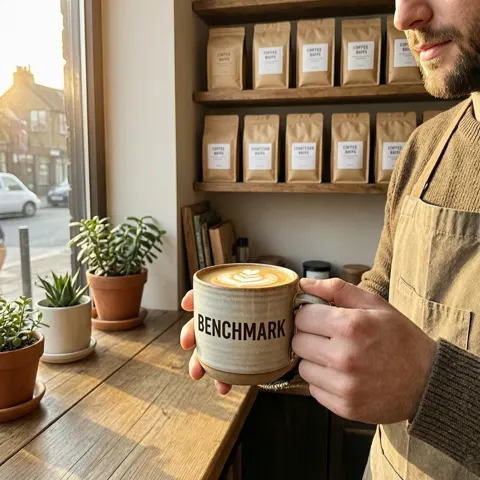
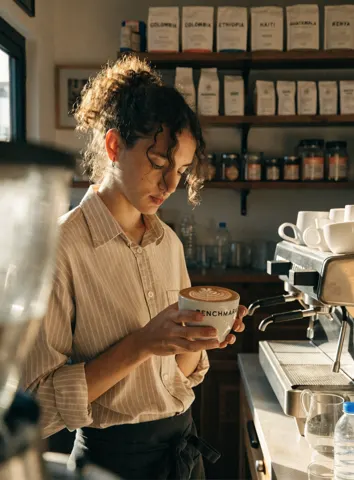
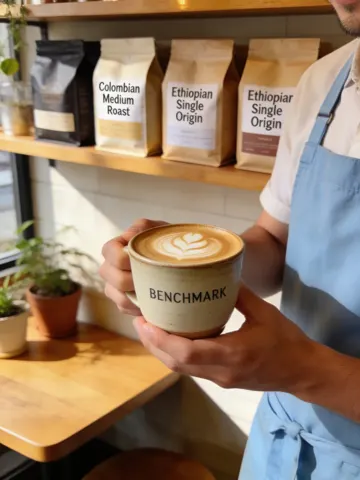
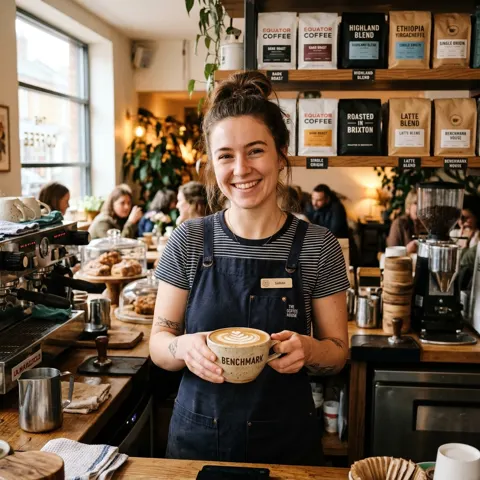
Image: "A barista in a cozy cafe holds a ceramic cup with the word 'BENCHMARK' printed on it, warm morning light, latte art visible, shelves of coffee bags with readable labels in the background, photorealistic"
Video: "A paper boat drifts down a rain-soaked city gutter at golden hour, slow tracking shot, reflections and ripples, cinematic"
The image prompt stresses four things at once: a printed word on a curved cup, hands holding it, a person's face, and small text on products in the background. The video prompt tests a small subject moving on water with a named camera move.
Settings
| Images | Video | |
|---|---|---|
| Models | 19 | 8 |
| Runs per model | 1 | 1 |
| Aspect ratio requested | 3:4 | 16:9 |
| Size / resolution | Each model's default | Lowest each model offers (480p–720p) |
| Length | — | 5 s (Veo 3.1 Fast: 4 s, its shortest) |
| Sound | — | Off (audio stripped from the clips shown) |
| Date | 2 November 2026 | 2 November 2026 |
What we recorded
- Credits: what each job was actually charged in Kenerate.
- Output: the pixel size of the file that came back.
- Time: seconds from the job starting to its file being saved, from the job's timestamps. It includes queueing, so treat it as rough.
- Checks: whether 'BENCHMARK' is spelled right and visible, and whether the coffee-bag labels can be read.
- One line on what went right or wrong. We don't give scores: one run can't justify them.
What's not in it
Models Kenerate sells under its own name were left out, so every result here is a named third-party model. MAI Image 2.5 failed twice and Luma Ray 3.2 failed once; Kenerate refunded those jobs, and they are not in the grid. 8 image models returned square images although 3:4 was requested; they are shown as they came back.
Image results
19 image models, one prompt
Sorted by credits charged, cheapest first. Yes / partial / no are our reading of the image, not a score.
| Model | Credits | Output · time | 'BENCHMARK' on cup | Bag labels readable | What we saw |
|---|---|---|---|---|---|
| Z Image Base · Alibaba Tongyi Lab | 3 | 1024×1024 (square) · ~26 s | Yes | No | Hand-lettered BENCHMARK, spelled right. Only a hand is shown, the thumb looks stretched, and the bag labels are made-up lettering. |
| MiniMax H3 Image · MiniMax | 6 | 896×1184 · ~11 s | Yes | No | Right word with slightly uneven letters. A first-person hand instead of a barista, and every bag label is gibberish. |
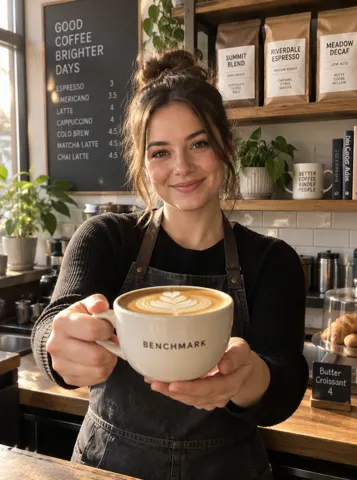
| GPT Image 2.5 Sunburst · OpenAI | 7.2 | 880×1184 · ~20 s | Yes | Yes | Clean cup text, readable bags (Summit Blend, Riverdale Espresso, Meadow Decaf) and a legible chalkboard menu it added itself. One book spine is garbled. |
| HiDream I1 Full · HiDream | 7.2 | 1024×1024 (square) · ~19 s | Yes | No | Crisp cup text and well-drawn hands, but the bag labels are blank and the light is cool and muted, not warm morning sun. |
| Kling Image v3 · Kuaishou | 8.4 | 896×1184 · ~15 s | Yes | No | Natural two-handed pose with a saucer and a believable face. Bag labels are there but too small to read; the light is flat. |
| Flux 2 Pro · Black Forest Labs | 9 | 1024×1024 (square) · ~10 s | Yes | No | Bold, clean cup text and a friendly portrait with steam. The bag labels are squiggles, and it came back square. |
| Qwen Image 3.0 · Alibaba | 9 | 887×1182 · ~10 s | Yes | No | Big, sharp cup text and good hands. The face is cropped out and the labels are too small to read. |
| Wan 2.7 · Alibaba | 9 | 1024×1024 (square) · ~25 s | Yes | Partial | Strong cup text and a nice street view. The bags literally read 'COFFEE BAGS', or misspellings of it; face cropped; square. |
| Recraft V4.1 · Recraft | 12 | 896×1216 · ~12 s | Partial | Yes | Spelled right, but a fingertip and the cup's curve hide the ends of the word. Small, real labels (Colombia, Ethiopia, Haiti, Kenya) and the most candid photo look. |
| Seedream 4.5 · ByteDance | 12 | 1728×2304 · ~14 s | Yes | Yes | Large, readable labels, though two bags repeat 'Ethiopian Single Origin' and one is cut off. Slightly soft; face cropped. Largest file in the test. |
| Seedream 5.0 Pro · ByteDance | 13.5 | 886×1182 · ~28 s | Yes | No | The most convincing morning light and very real hands, but the shelf is thrown out of focus, so no label can be read. |
| Nano Banana 2 · Google | 14 | 1024×1024 (square) · ~26 s | Yes | Yes | A busy, lifelike cafe with readable bag labels and shelf tags; the small print on the bags blurs. Came back square. |
| Ideogram v4 · Ideogram | 15 | 880×1168 · ~50 s | Yes | No | Crisp cup lettering and good hands, but a dim, out-of-focus shelf with unreadable labels, and an evening mood rather than morning. |
| Grok Imagine Image 2.0 · xAI | 15 | 1776×2368 · ~110 s | Yes | Yes | Sharp cup text and readable labels down to the tasting notes, in a convincing portrait. One label is clipped by the frame. Slowest image job. |
| GPT Image 2 · OpenAI | 18 | 768×1024 · ~39 s | Yes | Yes | Every bag is a real, readable coffee origin (Cerro Azul, Kenya Nyeri, Rwanda Musasa Natural), with natural hands and face. Smallest file in the test. |
| Krea 2 Large · Krea | 18 | 1024×1024 (square) · ~33 s | Yes | Partial | Bold cup text and a few readable labels (Cafe de Colombia, Washed, Ethiopia). The face is cut off at the eyes and the latte art is faint. |
| Flux 2 Max · Black Forest Labs | 21 | 1024×1024 (square) · ~24 s | Yes | Partial | Clean cup text and good hands. Labels are half real words ('Espresso Roast', 'Decaf') and half misspellings. Came back square. |
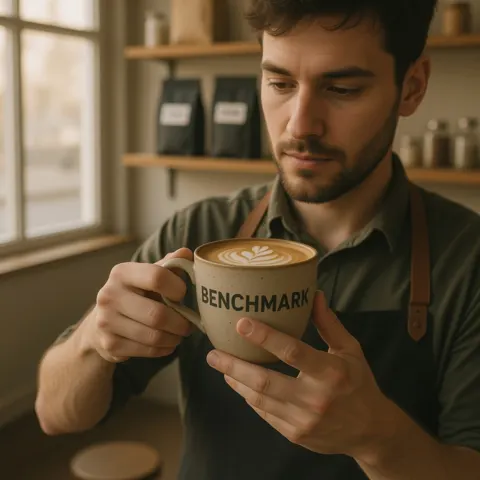
| Nano Banana 2.1 · Google | 21 | 896×1200 · ~51 s | Yes | Yes | Speckled stoneware mug with clean text and readable bags (Colombia, Ethiopia, House Blend), but the barista's head is cut off at the top. |
| Hunyuan Image 3 · Tencent | 30 | 1024×1024 (square) · ~8 s | Yes | No | Good cup text, hands and face, but no latte art and blank bag labels. The most expensive image here; came back square. |
19 images, 248.3 credits in total. One run per model, so a re-run can come out better or worse.
Every image
The image grid
Every first result, unedited, in the order of the table. Open one to see it full size with the prompt.
Video results
8 video models, one prompt
Text-to-video, 16:9, silent, the lowest resolution each model offers. Sorted by credits charged.
| Model | Credits | Output · time | What we saw |
|---|---|---|---|
| LTX 2.3 · Lightricks | 30 | 832×448 · 5 s · ~22 s to render | The gutter became a flooded avenue, and the boat warps into a cartoonish shape that swells toward the camera. Returned an audio track even with audio off. |
| MiniMax H3 · MiniMax | 50 | 832×480 · 5.2 s · ~16 s to render | A lovely silhouetted gutter with raindrop ripples, but the boat is a tiny pyramid, more paper hat than boat. |
| Pixverse v6 · PixVerse | 53 | 1024×576 · 5 s · ~47 s to render | Rich golden light, leaves and ripples, then a drain pipe appears mid-clip and the boat tips and changes size, so continuity breaks. |
| Wan 3.0 · Alibaba | 75 | 854×480 · 5 s · ~75 s to render | A convincing street with passers-by and reflections, but the boat mostly spins in place and its folds shift as it turns. |
| Seedance 2.0 Mini · ByteDance | 90 | 864×496 · 5 s · ~106 s to render | Closest to the prompt: a smooth, low tracking shot along a wet curb; the boat keeps its shape and a leaf drifts with it. |
| Veo 3.1 Fast · Google | 120 | 1280×720 · 4 s · ~54 s to render | A clean, stable boat with building reflections and raindrops, but it bobs in place with almost no drift. 4 s is its shortest length (4, 6 or 8 s). |
| Grok Imagine 1.5 · xAI | 120 | 752×416 · 5 s · ~41 s to render | Moody, backlit cobbles and ripples with a stable boat and a gentle drift. Lowest pixel count here, and it returned sound even with audio off. |
| Kling v3 Standard · Kuaishou | 126 | 1280×720 · 5 s · ~142 s to render | The most physical water: the boat sails away from a curb-level camera through warm building reflections and holds its shape. Slowest job. |
8 clips, 664 credits in total. We looked at each clip and at 6–12 frames per clip.
Every clip
The video grid
Hover or tap to play. Audio removed; re-encoded for the web.
Best for
Which model for what, from this run
Picks with the reason behind each. Test your own prompt on two or three of them before you commit.
Text and labels: GPT Image 2
The only model where every coffee bag was a real, correctly spelled origin. GPT Image 2.5 Sunburst got close for 7.2 credits and added a readable menu.
Light and mood: Seedream 5.0 Pro
The most believable morning light and hands, at 13.5 credits. It blurred the background, so pick another model when the labels matter.
Big files: Grok Imagine Image 2.0
1776×2368 by default with readable labels, the largest output here next to Seedream 4.5 (1728×2304). It was also the slowest image job.
Cheap drafts: Z Image Base
3 credits and the cup was spelled right. Expect made-up background text; MiniMax H3 Image (6) behaves the same way.
Camera moves: Seedance 2.0 Mini
The only clip with a real slow tracking shot while the boat kept its shape, for 90 credits at 480p.
Water and physics: Kling v3 Standard
The most physical ripples and reflections, at 720p for 126 credits. The camera barely moves, and it was the slowest job.
Do it yourself
How to run the same prompt on any model
- Time needed
- Steps
- 4 steps
- You need
- A web browser · A Kenerate account
Step 1
Open the image generator
Go to /app/image (or /app/video for the clip test) and sign in.
Step 2
Paste the benchmark prompt
Copy the exact prompt from this page and set the aspect ratio to 3:4 (16:9 for video).
Step 3
Pick a model and generate
Run it once, then switch the model and run the same prompt again.
Step 4
Compare the details
Zoom in on the cup text, the hands and the shelf labels; for video, watch the subject's shape and the camera move.
FAQ
AI model benchmark questions

Which AI image model is best at text in images?
In this run every one of the 19 models spelled 'BENCHMARK' on the cup, so a single short word no longer separates them. The background did: 7 models produced readable coffee-bag labels (GPT Image 2, GPT Image 2.5 Sunburst, Nano Banana 2, Nano Banana 2.1, Seedream 4.5, Recraft V4.1 and Grok Imagine Image 2.0), 3 were partly readable and 9 drew blank or made-up lettering. GPT Image 2 was the only one where every bag was a real, correctly spelled coffee origin.
Link to this answerWhat is the cheapest model that got the text right?
Z Image Base spelled the cup correctly for 3 credits, but its background labels were gibberish. The cheapest model that also kept the shelf labels readable was GPT Image 2.5 Sunburst at 7.2 credits, which also added a legible chalkboard menu.
Link to this answerWhich AI video model followed the prompt best?
Seedance 2.0 Mini (90 credits for 5 s at 480p) was the only clip with a real slow tracking shot along the gutter while the boat kept its shape. Kling v3 Standard (126 credits, 720p) had the most physical water and reflections but a mostly static camera. Veo 3.1 Fast was stable but the boat barely moved.
Link to this answerHow was the benchmark run?
One fixed image prompt and one fixed video prompt, each run once per model in Kenerate's generator on 2 November 2026, with default settings, aspect ratio 3:4 requested for images and 16:9 for video, the lowest resolution each video model offers, 5 seconds (4 s on Veo, which only offers 4, 6 or 8) and sound switched off. Nothing was cherry-picked, re-rolled or retouched.
Link to this answerWhy are some images square?
8 of the 19 models (Flux 2 Pro, Flux 2 Max, Nano Banana 2, Krea 2 Large, Hunyuan Image 3, HiDream I1 Full, Wan 2.7 and Z Image Base) returned a square 1024×1024 image although 3:4 was requested. We show them as they came back rather than re-running or cropping them, and the table lists every output size.
Link to this answerHow many credits did the whole benchmark cost?
912.3 credits: 248.3 for the 19 images and 664 for the 8 clips. The credits shown for each model are what that job was actually charged. Failed jobs (MAI Image 2.5 twice, Luma Ray 3.2 once) were refunded automatically and are not in the results.
Link to this answerDid the video models add sound?
We asked for silent clips. LTX 2.3 and Grok Imagine 1.5 still returned an audible audio track. To keep the comparison about the picture, the clips on this page have their audio removed and were re-encoded for the web.
Link to this answerIs this a ranking of the best AI model?
No. It is one prompt and one run per model, so luck matters and a different subject (anime, logos, products on white) would shuffle the order. Use it to see how each model handles text, hands, light and motion on the same brief, then test your own prompt on the two or three that fit.
Link to this answerCan I run the same prompt myself?
Yes. Both prompts are on this page; paste them into the image or video generator and pick any model. Of the image models tested, Qwen Image 3.0 is usable on the free plan; video generation needs a paid plan, and one-time credit packs never expire.
Link to this answer
Try the same prompt
Paste the benchmark prompt, pick a model, and see if you agree with us.



By the Kenerate AI teamLast updated and reviewed
We build Kenerate AI and ran every job on this page ourselves in Kenerate's generator. Credits, sizes and times come from the job results; the notes are what we saw.
Sources: Kenerate image generator (where the image runs were made) · Kenerate video generator (where the clips were made) · Kenerate pricing and credit packs